Project 4, Part 2: Placement, CTS, Routing, and Timing Closure
In the previous article we floorplanned the RISC core at 55% utilisation. This is the project where the flow pushes back. Projects 1 to 3 either worked first time or needed one small fix. This one needs two real interventions, one at placement and one at signoff timing, and neither is staged: they are the problems a design of this size, at this utilisation, with a control-heavy netlist, actually produces.
Placement: the first problem
openlane --flow Classic --run-tag cpu_run1 --from OpenROAD.GlobalPlacement --to OpenROAD.GlobalRouting \
         designs/cpu_top/config.json
Placement itself finishes and legalises every cell. The trouble shows up in the global routing that follows, whose congestion report, trimmed, reads:
[INFO GRT-0096] Final congestion report:
Layer         Resource        Demand        Usage (%)    Max H / Max V / Total Overflow
---------------------------------------------------------------------------------------
met1             81210         64830           79.83%           212 /  0 / 212
met2             80544         52170           64.77%             0 / 88 /  88
met3             57960         21044           36.31%             0 /  0 /   0
...
Total           ...                                             212 / 88 / 300
[WARNING GRT-0115] Global routing finished with overflow.
300 routing cells with more demand than capacity on met1 and met2. The congestion map in the GUI puts almost all of it in one area: the middle of the core, where the placer packed the control state machine and the memories’ read multiplexers. Those parts of the design have dense, irregular connectivity, many signals fanning into wide multiplexers, and they concentrate routing demand in a small area even though the design’s average utilisation of 55% looks reasonable.
Average utilisation is a die-wide number, while congestion is local. A comfortable average can hide an overloaded region, which is why Module 4 treats congestion analysis as its own check rather than reading it off the utilisation.
The fix: routability-driven placement, not a global density cut
The tempting fix is to lower PL_TARGET_DENSITY for the whole design. That spreads every region out, including all the ones that were never a problem, and spends area everywhere to fix one spot. The targeted fix is the one we switched off in the previous article. Routability-driven placement runs a quick global route during placement, finds the congested regions and inflates the cells there, so the placer spreads out only those areas:
"PL_ROUTABILITY_DRIVEN": true
Re-running from global placement, global routing now reports no overflow, and the total wirelength is about 2.7% higher than before. Spending a little wirelength to buy a routable placement is almost always the right trade, as Module 4 said.
CTS and routing
openlane --flow Classic --run-tag cpu_run1 --from OpenROAD.CTS designs/cpu_top/config.json
[INFO CTS-0010] Clock net "clk" has 612 sinks.
Max skew: 0.198 ns
Max latency: 0.890 ns
The detailed router needed three optimisation passes to reach zero violations, against two in Project 3 and one or two in the earlier projects. The routability fix helped, but a design this size at 55% was never going to route as easily as the small ones. Zero violations at the end is a full pass, only harder won.
Signoff timing: the second problem
The flow’s multi-corner STA, on the extracted parasitics, passes at tt and ff and fails at ss. Here is the failing path at the slow corner, next to the same path at typical (simplified):
Startpoint: ctrl/state_reg[2]      Endpoint: alu_b_sel_reg      Path Type: max

                                          tt_025C_1v80     ss_100C_1v60
  clock latency at launch flop                0.890            0.890
  clock to Q                                  0.145            0.312
  decode logic (11 levels, 2 high-fanout)     7.470           12.840
  data arrival time                           8.505           14.042

  clock period                               12.000           12.000
  clock latency at capture flop               0.912            0.912
  clock uncertainty + setup                  -0.310           -0.310
  data required time                         12.602           12.602

  slack                                      +4.097           -1.440
The same path, the same logic, a comfortable +4.1 ns at typical and 1.44 ns short at the slow corner. The decode logic is 72% slower at ss than at tt, which is in the normal range for this process, and on a path this long that is enough to blow through the period. This is Module 7’s point about corners on a real design: a path with plenty of typical-corner slack can still be the one that blocks signoff.
(The clock latencies are shown the same at both corners for simplicity; in a real report they differ too.)
The cause
Eleven levels of logic between two flops, inside the control unit, from the opcode to the ALU’s B-input select, with two high-fanout nets along the way. That is a long chain for what is logically a simple decode, and it is the result of the control state machine’s output logic being written as one flat block of combinational logic in the RTL. Physical design cannot undo that; it can only make the chain faster.
The fix: a targeted ECO
Re-pipelining the control logic is an RTL change, outside the scope of a physical design fix. What we can do is the Module 7 ECO: upsize and buffer the cells on this path. In an OpenROAD session on the routed design, with all three corners loaded as in Module 7:
% repair_timing -setup -setup_margin 0.1
The resizer upsizes several gates on the path and buffers one of the high-fanout nets, and gains 1.18 ns at the slow corner: slack goes from −1.44 to −0.26 ns. Not enough. Looking at the report again, one NAND gate driving the second high-fanout net was left at its smallest size, because upsizing it would have slowed a different, parallel path the resizer was protecting. Checking that other path by hand shows it has several nanoseconds of slack, so we make that change ourselves:
% replace_cell ctrl/_1532_ sky130_fd_sc_hd__nand2_4
Then legalise, re-route the changed nets and re-extract, as in Module 7, and run the three corners again:
| Corner | Worst setup slack | Worst hold slack |
|---|---|---|
tt_025C_1v80 |
+4.47 ns | +0.14 ns |
ss_100C_1v60 |
+0.09 ns | +0.21 ns |
ff_n40C_1v95 |
+5.31 ns | +0.05 ns |
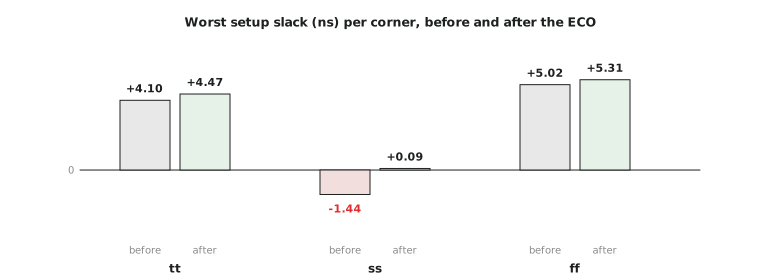
All three corners pass, the slow one by a thin +0.09 ns, as Figure 1 shows. That is the kind of margin Module 7 says is worth flagging to a reviewer even though it passes: a path this close to zero has no room left for anything else to go wrong on it, and with derating applied as in Module 7 it would likely fail again. In a real project I would take this back to the RTL owner and ask for the decode to be split across two cycles.
The mistake this project shows so clearly is treating a typical-corner pass as proof that a design is done. This path passed typical with 4.1 ns to spare and would have gone to the fab as a real violation if signoff had stopped there. The slow corner is not a formality; it is often where the real violation lives.
Practice Exercise
The final slow-corner slack is only +0.09 ns. Give one reason, to do with variation, why a real chip might still fail timing in use even though signoff reported a positive number.
Solution
The ss_100C_1v60 corner is one fixed, pessimistic combination of process, temperature and voltage, but real variation is continuous. Within a single die, some cells are slower than the library’s slow corner says, the on-chip variation of Module 7, and the supply at this part of the chip is lower than nominal by the local IR drop. With only 90 ps of margin on a 14 ns path, 1% extra delay is enough to use it up.
This is why real signoff flows apply derating or statistical methods on top of the corners, and why a tapeout decision with 90 ps of margin on a path this long would normally lead to either an RTL fix or an explicit, written acceptance of the risk, not a quiet signoff.
Two real problems and two real fixes: congestion in the control logic, solved by turning on routability-driven placement, and a slow-corner setup violation on a long decode chain, closed by an ECO in two steps. In the next article we run the full physical verification on the finished core and write the most complete signoff report of the course.