A Pipelined Multiply-Accumulate Unit
The last three articles covered stage balancing, inserting stages and stalling. This article puts them together in one design.
$a \times b + \text{acc} \rightarrow \text{acc}$ is the entire content of a multiply-accumulate, or MAC, unit. It is also the most repeated operation in every FIR filter, every matrix multiply and every neural network accelerator. If you end up in DSP or accelerator work you will build one of these, in some form, more often than almost anything else.
The specification
- Two operands,
aandb, arrive together with avalid_inflag. - The unit computes
a * band adds it to a running accumulator. - A
clear_accinput starts a new accumulation on the same cycle as the operands it arrives with. - A
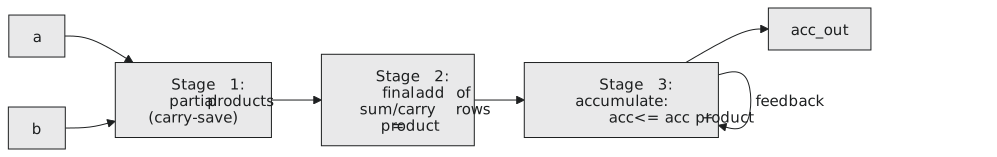
stallinput freezes the whole pipeline, as in the previous article. - Three stages: the multiply is split across two (as in Section 7.2) and the accumulate is the third.
Why the accumulator is the interesting part
A pipelined multiplier followed by a pipelined adder is Section 7.2 done twice. What makes a MAC new is the feedback: the accumulator’s own previous output is one input to the final add, every cycle. Get the timing wrong and you do not get one wrong answer, you get compounding wrong answers, because every later accumulation builds on the corrupted one.
The design
`timescale 1ns / 1ps
`default_nettype none

module mac_unit #(parameter WIDTH = 16) (
    input  wire                    clk, rst_n,
    input  wire                    stall,
    input  wire                    clear_acc,
    input  wire [WIDTH-1:0]        a, b,
    input  wire                    valid_in,
    output reg  [2*WIDTH-1:0]      acc_out,
    output reg                     valid_out
);
    localparam H = WIDTH / 2;

    // ---- Stage 1: partial products (the two rows, as in Section 7.2) ----
    reg [2*WIDTH-1:0] pp_lo, pp_hi;
    reg               valid_s1, clear_s1;

    always @(posedge clk or negedge rst_n) begin
        if (!rst_n) begin
            pp_lo <= 0; pp_hi <= 0; valid_s1 <= 1'b0; clear_s1 <= 1'b0;
        end else if (!stall) begin
            pp_lo    <= a * b[H-1:0];
            pp_hi    <= (a * b[WIDTH-1:H]) << H;
            valid_s1 <= valid_in;
            clear_s1 <= clear_acc;   // clear_acc must ride the pipeline too: passthrough
        end
    end

    // ---- Stage 2: final add -> product ----
    reg [2*WIDTH-1:0] product_reg;
    reg               valid_s2, clear_s2;

    always @(posedge clk or negedge rst_n) begin
        if (!rst_n) begin
            product_reg <= 0; valid_s2 <= 1'b0; clear_s2 <= 1'b0;
        end else if (!stall) begin
            product_reg <= pp_lo + pp_hi;
            valid_s2    <= valid_s1;
            clear_s2    <= clear_s1;   // still riding along
        end
    end

    // ---- Stage 3: accumulate, the feedback stage ----
    always @(posedge clk or negedge rst_n) begin
        if (!rst_n) begin
            acc_out   <= {2*WIDTH{1'b0}};
            valid_out <= 1'b0;
        end else if (!stall) begin
            if (clear_s2)
                acc_out <= product_reg;                 // start a new accumulation
            else if (valid_s2)
                acc_out <= acc_out + product_reg;        // continue accumulating
            // if neither: hold acc_out (a bubble passed through)
            valid_out <= valid_s2;
        end
    end
endmodule
Three things are worth stopping on.
clear_acc had to become a passthrough, threaded through every stage like the carry in Section 7.2. It arrives with a and b on cycle 0, but the accumulator does not act on it until cycle 2, when the matching product is ready. Without clear_s1 and clear_s2, the clear would be applied against the wrong product, which is exactly the bug the retrofit checklist warned about.
The accumulate step checks clear_s2 before valid_s2. Starting a fresh accumulation and continuing one are different operations, and the if/else if order says which wins if both are set on the same cycle. Clearing takes priority, matching the reset-beats-enable convention from Section 5.5.
A bubble, a cycle where valid_s2 and clear_s2 are both 0, leaves acc_out untouched. That is not an accident: it falls out of the if/else if having no final else, which as you know from Section 5.3 infers “hold the current value”, which is what a register should do here.
Self-checking testbench
module tb_mac_unit;
    parameter WIDTH = 8;
    reg clk = 0, rst_n, stall, clear_acc, valid_in;
    reg [WIDTH-1:0] a, b;
    wire [2*WIDTH-1:0] acc_out;
    wire valid_out;

    mac_unit #(.WIDTH(WIDTH)) dut (
        .clk(clk), .rst_n(rst_n), .stall(stall), .clear_acc(clear_acc),
        .a(a), .b(b), .valid_in(valid_in),
        .acc_out(acc_out), .valid_out(valid_out)
    );

    always #5 clk = ~clk;

    // Present one operand pair for exactly one clock edge
    task feed;
        input [WIDTH-1:0] av, bv;
        input clr;
        begin
            a = av; b = bv; clear_acc = clr; valid_in = 1;
            @(negedge clk);
        end
    endtask

    integer errors = 0;

    initial begin
        $dumpfile("tb.vcd");
        $dumpvars(0, tb_mac_unit);

        rst_n = 0; stall = 0; clear_acc = 0; valid_in = 0; a = 0; b = 0;
        @(negedge clk); rst_n = 1;

        // Accumulate: 3*4 + 5*6 + 2*2 = 12 + 30 + 4 = 46
        feed(3, 4, 1);   // clear_acc=1: starts a fresh accumulation with this product
        feed(5, 6, 0);
        feed(2, 2, 0);
        valid_in = 0; clear_acc = 0;

        // The last pair entered stage 1 at the edge just passed; it needs two
        // more edges to reach the accumulator. Check on the cycle it lands.
        repeat (2) @(negedge clk);

        if (acc_out == 46 && valid_out == 1'b1)
            $display("PASS: acc_out=%0d valid_out=%b on the expected cycle", acc_out, valid_out);
        else begin
            $display("FAIL: acc_out=%0d valid_out=%b (expected 46, 1)", acc_out, valid_out);
            errors = errors + 1;
        end

        // Stall test: let a fresh accumulation land, then freeze and check nothing moves
        feed(10, 10, 1);   // fresh accumulation: 100
        valid_in = 0; clear_acc = 0;
        repeat (2) @(negedge clk);          // 100 now sits in acc_out with valid_out = 1
        stall = 1;
        repeat (3) @(negedge clk);          // three edges while stalled
        if (acc_out !== 100 || valid_out !== 1'b1) begin
            $display("FAIL: outputs changed during stall, acc_out=%0d valid_out=%b", acc_out, valid_out);
            errors = errors + 1;
        end
        stall = 0;
        @(negedge clk);
        if (valid_out !== 1'b0) begin       // the empty slot behind it now drains through
            $display("FAIL: valid_out should drop after the stall is released");
            errors = errors + 1;
        end

        if (errors == 0) $display("ALL TESTS PASSED");
        else $display("%0d TEST(S) FAILED", errors);

        $finish;
    end
endmodule
Two things this testbench checks that a weaker one would skip. It checks the exact cycle the result lands on, tied to the pipeline’s known 3-cycle latency, rather than waiting “long enough”. And it checks that asserting stall freezes both acc_out and valid_out for the whole stall, and that the pipeline resumes correctly afterwards.
This structure, pipelined multiply into a stall-aware accumulator with a feedback path, is the cell of a systolic array, which is the architecture under most dedicated neural network accelerators. A systolic array tiles thousands of these together and passes partial sums between neighbours on every clock edge.
Practice Exercise
Add an overflow output that asserts if the accumulator would exceed its 2*WIDTH-bit range on an accumulate step. Decide which overflow rule from Section 7.2 applies, and make sure overflow is pipelined correctly if you report it registered.
Solution
reg overflow_out;

always @(posedge clk or negedge rst_n) begin
    if (!rst_n) begin
        acc_out <= {2*WIDTH{1'b0}};
        valid_out <= 1'b0;
        overflow_out <= 1'b0;
    end else if (!stall) begin
        if (clear_s2) begin
            acc_out      <= product_reg;
            overflow_out <= 1'b0;   // starting fresh can't overflow
        end else if (valid_s2) begin
            // acc_out and product_reg are unsigned here, so the carry out of
            // the top bit is the overflow indicator.
            {overflow_out, acc_out} <= {1'b0, acc_out} + {1'b0, product_reg};
        end
        valid_out <= valid_s2;
    end
end
Because this MAC treats its accumulator as unsigned, the check is the plain carry-out from the unsigned saturating adder in Section 7.2, not the same-sign-in, opposite-sign-out rule, which applies only to signed values. A signed version of the MAC would need the signed rule instead. Which overflow rule is right always depends on which arithmetic domain you are in.
The MAC unit pulls Section 7.3 together: balanced stages carrying a multiply from Section 7.2, a clear_acc passthrough crossing the same boundaries a carry or a valid bit would, and a stall that freezes a feedback path correctly. That closes the arithmetic and pipelining half of this module. In the next article, Section 7.4 turns to a different kind of buffer, the FIFO, where the depth is not a fixed number of stages but however much data happens to be waiting.